
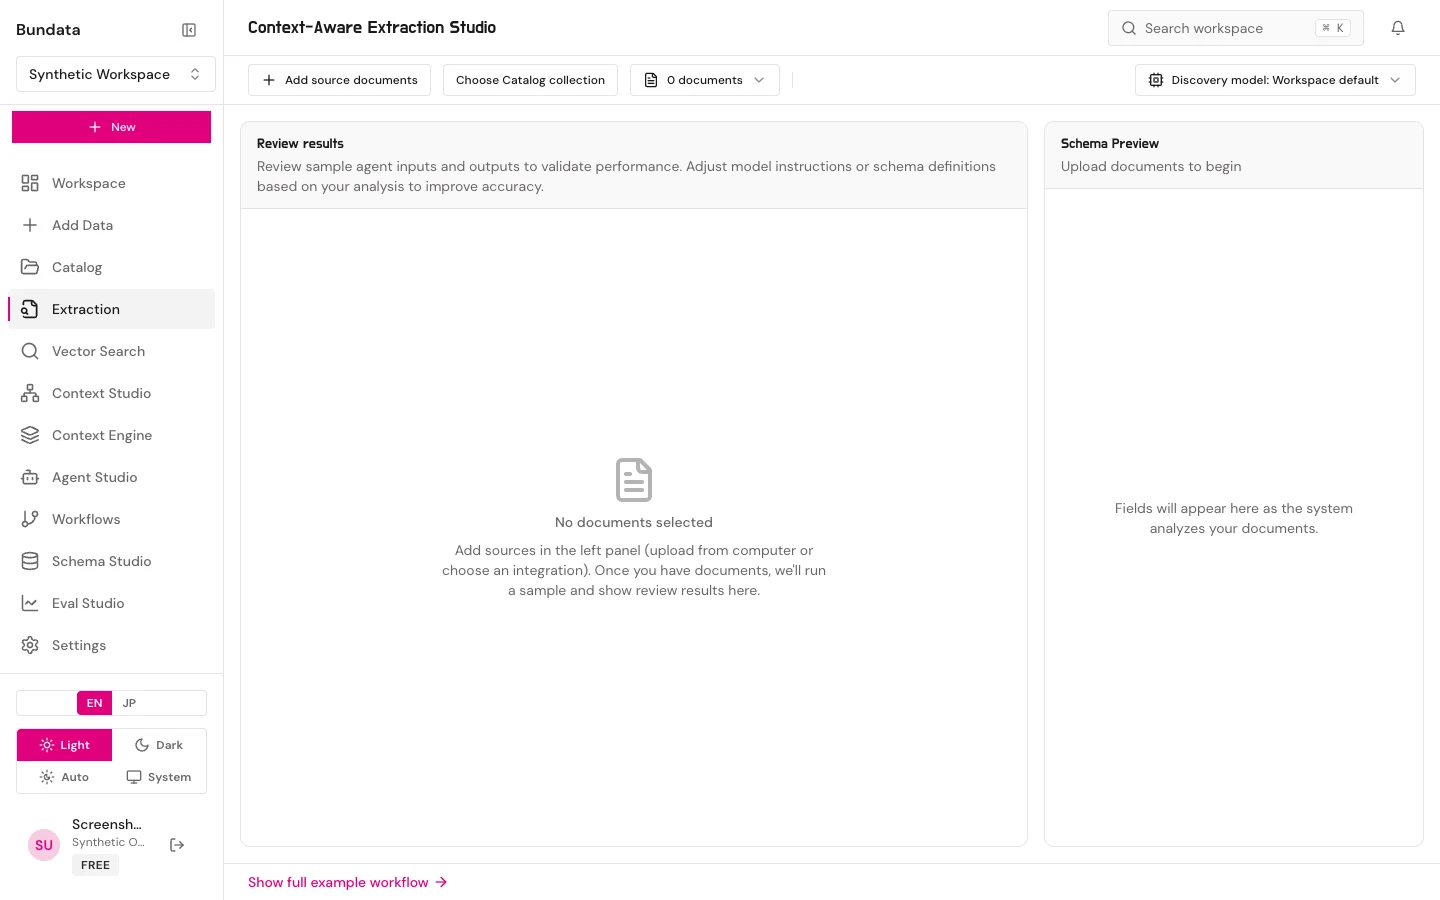
Extraction fills an approved schema, records normalized field values with citations, and emits main and multi-size Smart Bites.
Extraction overview
Prerequisites
Stored workspace, readable documents, an approved schema, and a role that can run extraction. You can choose a specific discovery model (discoveryModel) or extraction agent model (extractionModel) from OpenAI, Anthropic, or Google, or leave the picker on Workspace default (configured in Settings → AI models). A chosen model whose provider is disconnected or unapproved is refused before any document is processed (MODEL_CHOICE_UNAVAILABLE, MODEL_NOT_APPROVED).
Output
A saved run (agent_runs, recording the model provenance in extraction_model_json), normalized studied field values with verified passage span citations (field_value_citations), and Smart Bites tied to source documents.
New collections default to the 3-size chunking preset (three_sizes: main chunks at 1,500 characters with paragraph boundaries, plus derived 500-character sentence groups and 4,500-character multi-chunk windows). You can preview and adjust chunk sizes (single, three_sizes, or custom from 100 to 12,000 characters) in Extraction Studio or on the collection page. Discovered collections also enable vocabulary rules automatically during retrieval.
Failure
Status error, or a queue code such as DOCUMENT_PROCESSING_QUEUE_UNAVAILABLE, means the run did not finish. Retry the same job when the message says to. Do not invent a success from a saved draft agent.