
Compare runs you already have.
Evaluation
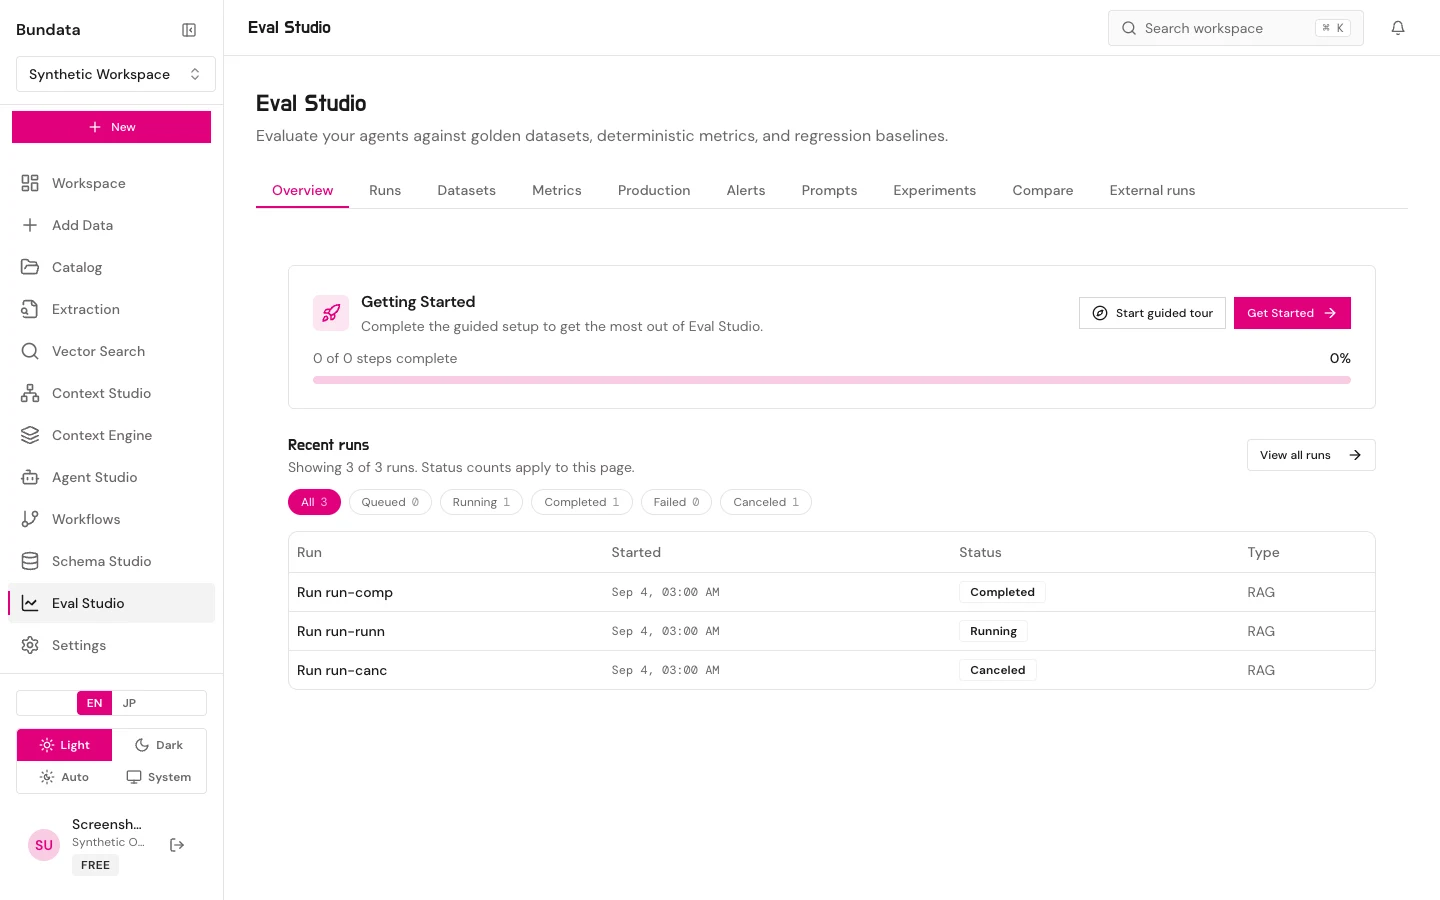
Start from Overview
The getting-started card counts setup steps. Completing steps is not an evaluation result. Recent runs show status for the runs already on this page.
What each tab holds
Runs starts an evaluation against a finalized dataset version and a metric collection. Datasets freeze golden cases. Metrics group the signals a run applies. Production lists traces and can turn real executions into goldens. Query text is not stored in those traces. Alerts watch production metrics. Prompts version the templates. Experiments compare prompt versions. Compare places two completed runs side by side.
Saved is not executed
A dataset, metric collection, prompt, or alert that is only saved has not scored anything. Open Runs and read the status before you treat a number as a result. QA harness URLs are not part of this product.