
Each answer request carries its own query and freshly confirmed evidence. History is not a source.
Repeated questions
Ask a second question after the first grounded answer, and see that the API does not receive your chat log unless you put it in query. Hands-on time is about 15 minutes.
Purpose
You can describe a follow-up without inventing memory. Level: same as Scoped search. There is no MongoDB Atlas connector and no chat-message import.
Prerequisites
You already hold one grounded result and its evidence refs. Those refs may go stale. Plan to search again.
Sample
First query: the 14-day window. Second query: Who pays for late Harbor Sample delivery? The note does not say. Expected status: insufficient_evidence. Do not let a model invent a party.
Steps
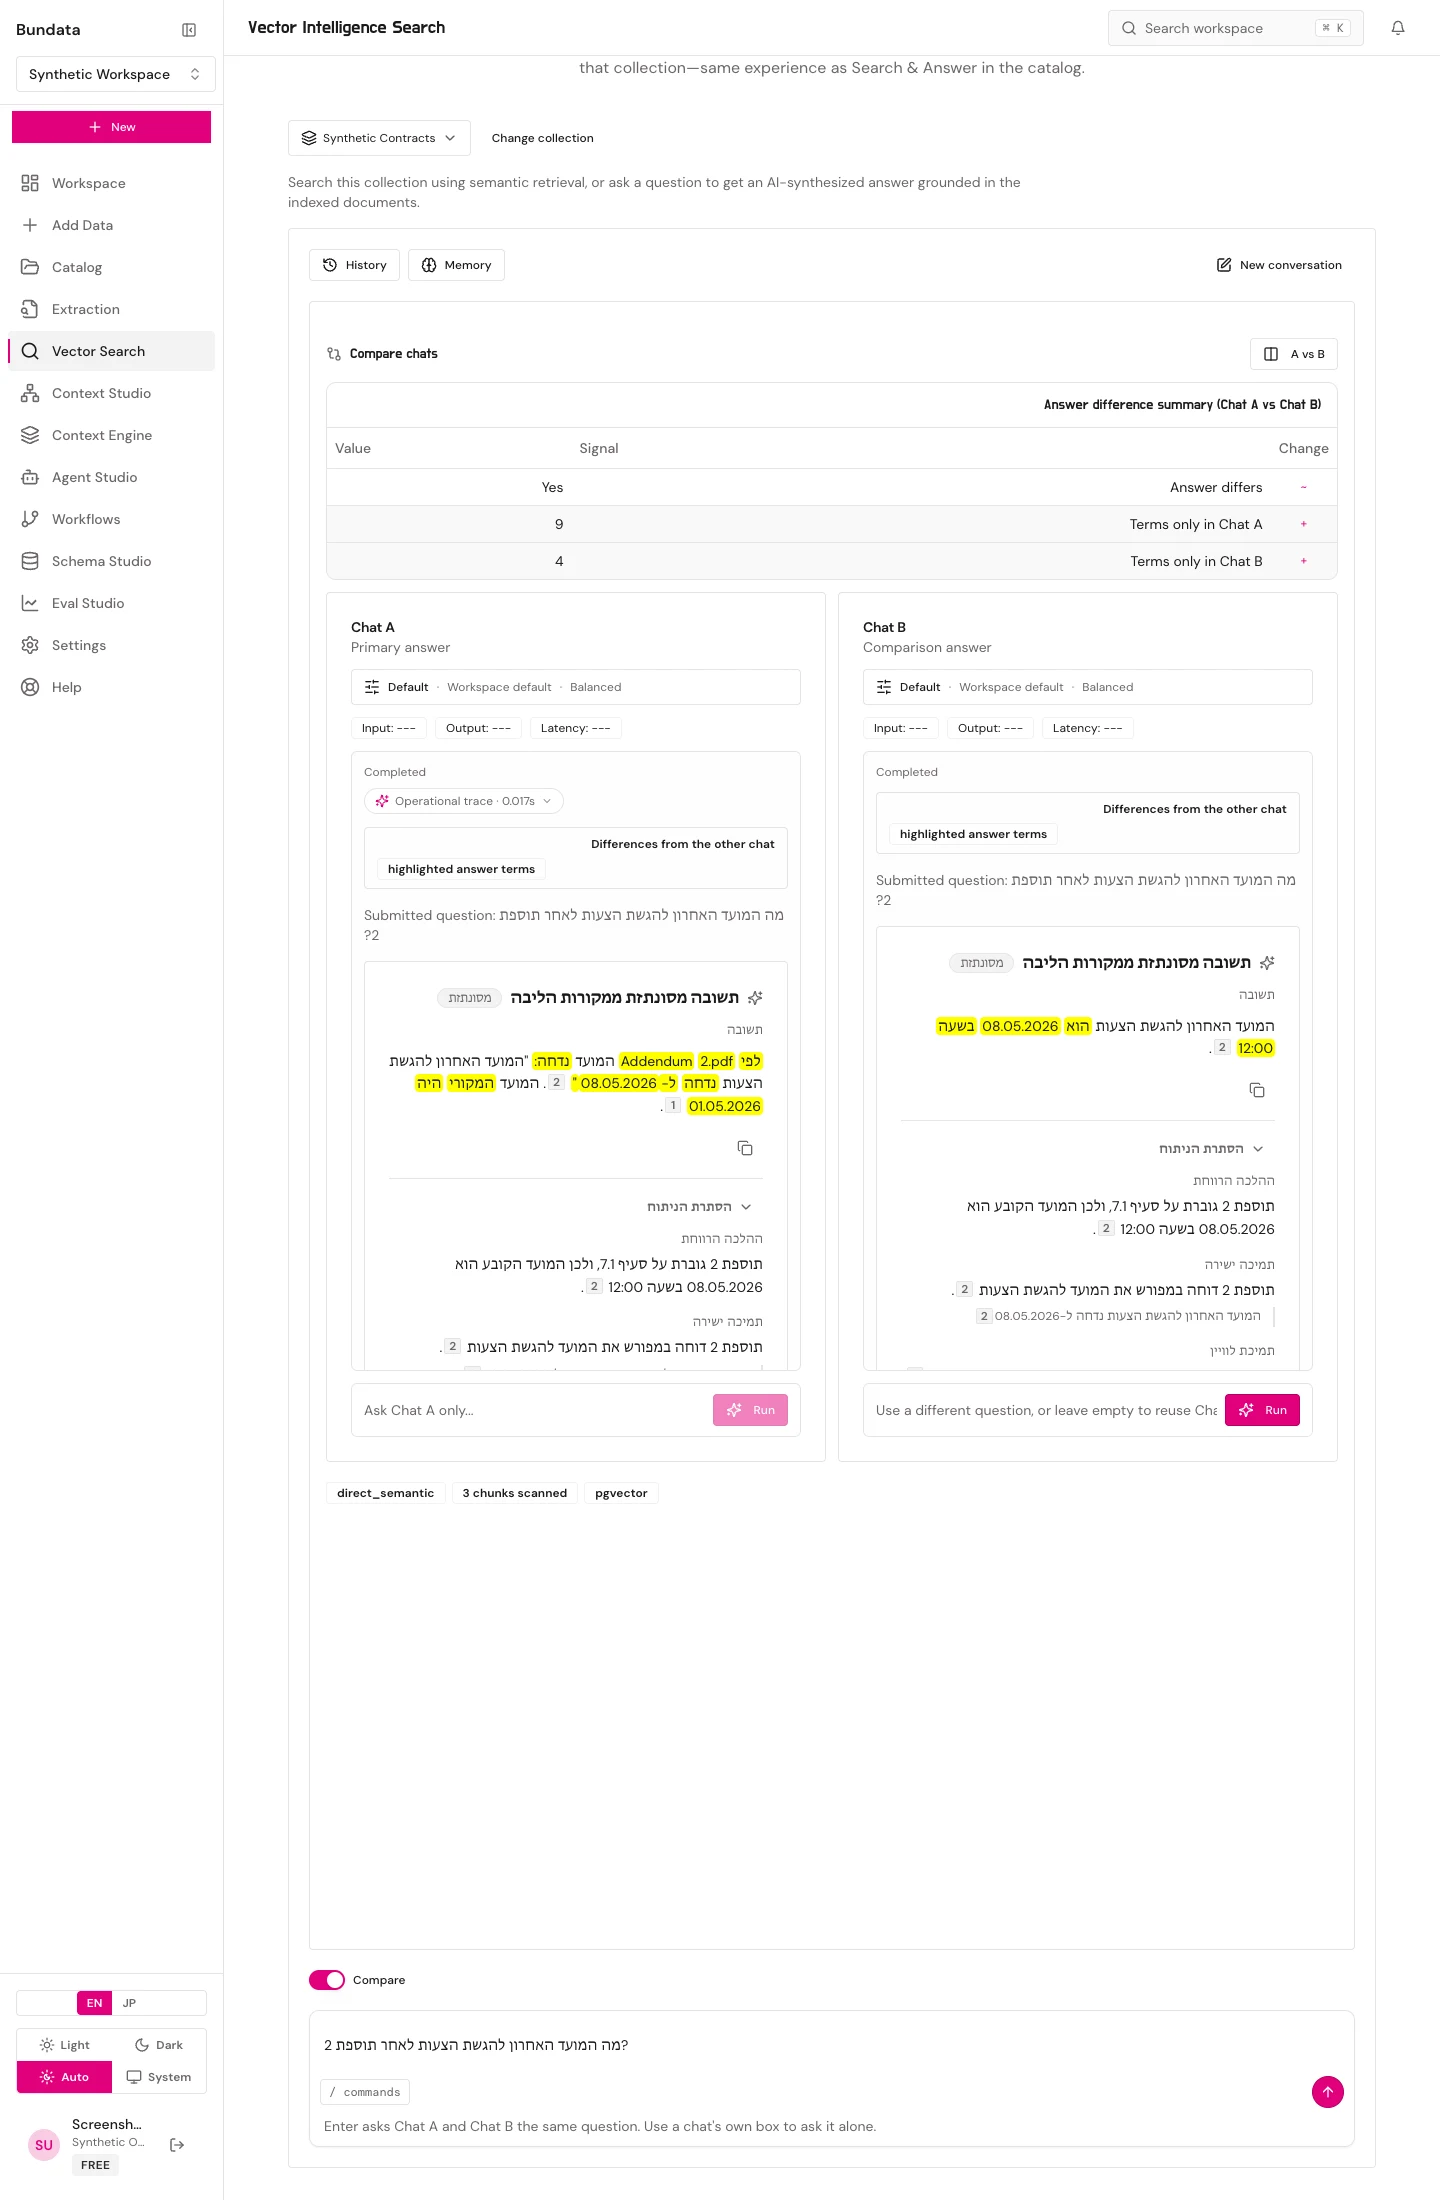
- On Search and Answer, send the second question as a new question. Compare mode runs Chat A and Chat B separately. Empty Chat B reuses Chat A’s question only as a form default, not as retrieved memory.
- For HTTP, send a new
POST /searchwith the new query text. Then confirm the new refs. The previous answer body is not attached. - If your own application stores the prior answer, label that store as yours. It is not Bundata evidence. Do not place it in
evidenceRefs. - If you fold the prior answer into
query, the model may see your text, and citations still have to come from confirmed bites.
Fields
| You send | The service treats it as |
|---|---|
New query | The question for this call only. |
New evidenceRefs | The only passages an answer may cite. |
| Your database of old answers | Out of band. Not a bite. |
| Atlas collection or chat-message JSON | Not a Bundata ingest. |
Example
{"query":"Who pays for late Harbor Sample delivery?","confirmed":true,"evidenceRefs":["paste-a-current-ref"]}Recovery
Stale refs return source_changed. Search again. If the note has no payer, accept insufficient_evidence. Do not retry until the model guesses.
Limits
Workspace search (POST /api/w/{workspaceId}/search/answer) is stateless per request unless you fold context into query, and there is no MongoDB Atlas source. In contrast, the collection Ask tab (POST /api/collections/{id}/answer) keeps private per-member Ask history and standing notes in stored workspaces, and external agents can use Governed agent memory (/api/agent/v1/memories/*). Even there, earlier answers and agent memories are context only—never evidence—and every claim must still cite a current passage.
Check
Success: the second call’s citations, if any, come from refs you confirmed for that call. Failure: a payer name with no citation is rejected by you, and the status you record is insufficient.