
This is the lab on the Search tab. The five stages are Understanding question, Retrieving sources, Ranking and evidence, Analyzing documents, and Synthesizing a
Context Policy
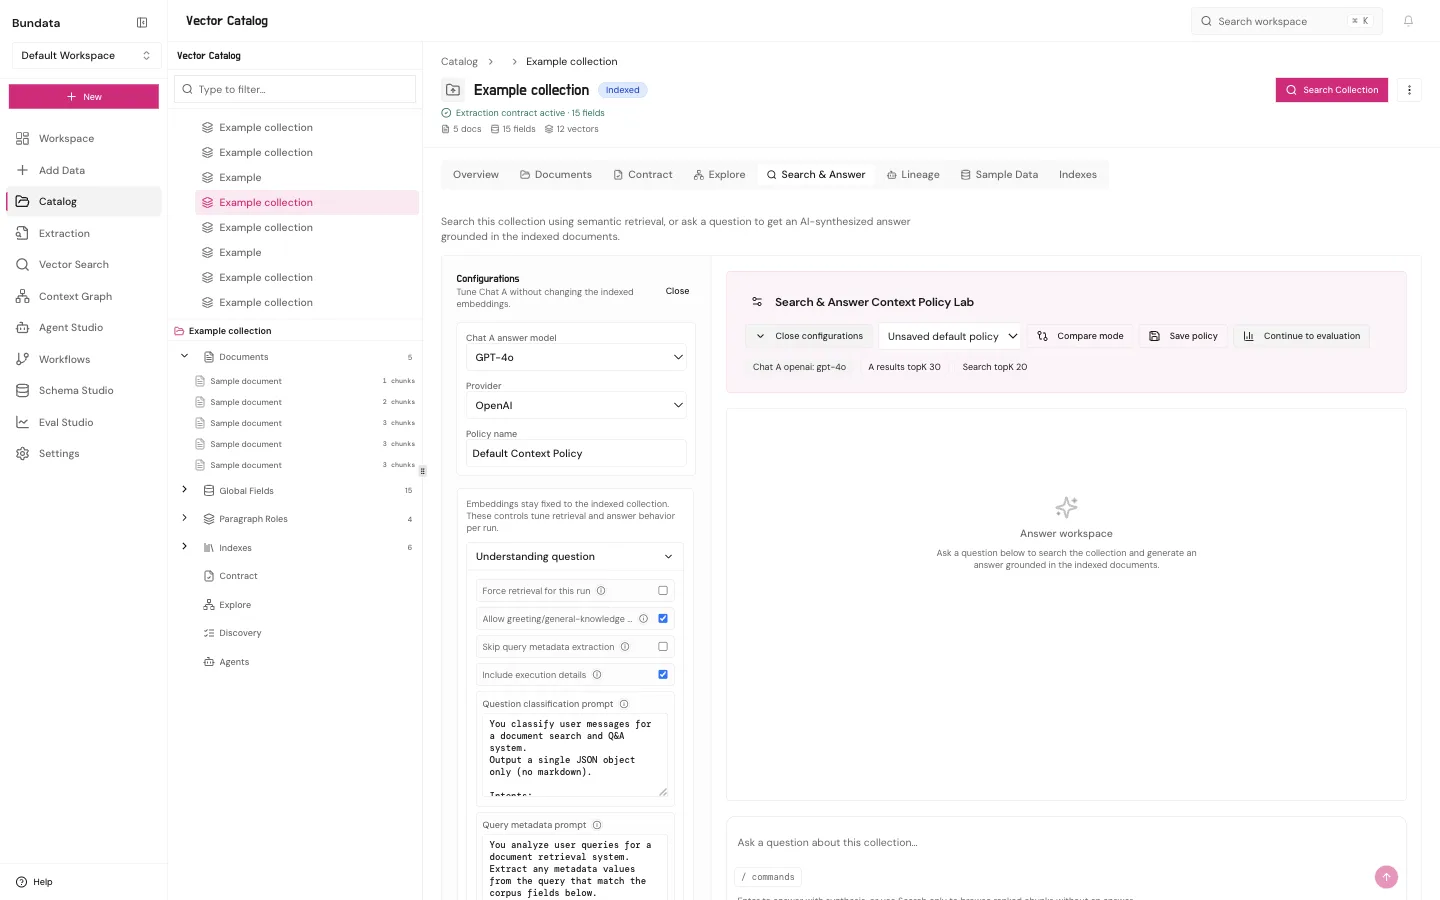
This is the lab on the Search tab. The five stages are Understanding question, Retrieving sources, Ranking and evidence, Analyzing documents, and Synthesizing answer. Embeddings stay fixed to the indexed collection. The policy tunes the next retrieval and answer. It does not change an existing answer or the vectors. Choosing a model name does not provision a key and does not mean that model is available.
Stages
Open configurations to see the stages. Chat A and Chat B are edited separately. Copy Chat A settings to Chat B copies the form. It does not run either side.
Fields
| Visible label | Key | Type | Form start | API bounds | Next run |
|---|---|---|---|---|---|
| Policy name | policyName | string | Default Context Policy | 1–180 characters | Sent as the policy name. Does not change embeddings. |
| Provider | policySnapshot.modelProvider | enum openai | anthropic | google | openai | Those three values | Selects the answer provider for the next run. It does not provision a key. |
| Chat A answer model | policySnapshot.model | string | gpt-4o | 1–160 characters | Catalog answer model (synthesis step) for Chat A, or empty for the workspace default. Honored or refused (MODEL_NOT_IN_CATALOG, MODEL_CHOICE_UNAVAILABLE, MODEL_NOT_APPROVED), never swapped. |
| Chat B answer model | policySnapshot.model | string | gpt-4o-mini | 1–160 characters | Used only for the Compare side. Can compare across OpenAI, Anthropic, and Google. |
| Mini-query provider and model | miniQueries.provider, miniQueries.model | enum / string | workspace default | catalog query_expansion models | Optional model choice for mini-query expansion. Checked before retrieval runs. |
| Temperature | policySnapshot.temperature | number | 0.25 | 0–2 | Changes how varied the next answer is. Does not change the index. |
| Search results topK | policySnapshot.searchTopK | integer | 20 | 1–50 | Search only. Ignored by Answer, which uses Answer results topK. |
| Answer results topK | policySnapshot.retrievalTopK | integer | 30 | 1–50 | How many ranked chunks Answer and Compare reveal. |
| Force retrieval for this run | understanding.forceRetrieval | boolean | off | — | Always retrieves, even for a greeting. |
| Allow greeting/general-knowledge short circuit | understanding.allowShortCircuit | boolean | on | — | Lets the classifier skip the corpus for greetings. |
| Skip query metadata extraction | understanding.skipQueryMetadataExtraction | boolean | off | — | When on, the query-metadata prompt is not used. |
| Include execution details | policySnapshot.includeExecutionDetails | boolean | on | — | Shows diagnostics such as mini queries. Not a quality score. |
| Question classification prompt | understanding.classificationPrompt | string | locale default text | max 12000 | Omitted from the snapshot when the text equals the English default. |
| Query metadata prompt | understanding.queryMetadataPrompt | string | locale default text | max 12000 | Ignored while Skip query metadata extraction is on. |
| Generate mini queries | miniQueries.enabled | boolean | on | — | When off, mini-query count, limit, threshold, and prompt are ignored. |
| Mini-query count | miniQueries.count | integer | 5 | 0–12 | Ignored until Generate mini queries is on. |
| Mini-query limit | miniQueries.limit | integer | 20 | 1–200 | Ignored until Generate mini queries is on. |
| Mini-query threshold | miniQueries.scoreThreshold | number | 0.2 | 0–1 | Ignored until Generate mini queries is on. |
| Mini-query prompt | miniQueries.promptOverride | string | locale default; placeholders question and count | max 12000 | Omitted when equal to the English default. Ignored when mini queries are off. |
| not a separate labeled stage control | miniQueries.discount | number | 0.82 | 0–2 | Serialized with the snapshot. It is not one of the five stage titles. |
| Evidence mode | evidence.mode | enum strict | balanced | broad | balanced |
| Embedding boost | reranking.embedBoost | number | 0.7 | no extra bound in the schema | Weight on embedding similarity. Does not re-embed. |
| Temporal boost | reranking.temporalBoost | number | 0.15 | no extra bound in the schema | Weight on recency when that signal exists. |
| Rerank candidate topK | reranking.topK | integer | 30 | 1–200 | Candidates reranked. It does not by itself raise the Answer result count. |
| Enable evidence extraction | evidence.extractionEnabled | boolean | on | — | When off, evidence limits and the evidence prompt are ignored. |
| Primary evidence max | evidence.primaryMax | integer | 8 | 0–30 | Ignored until evidence extraction is on. |
| Supplementary evidence max | evidence.supplementaryMax | integer | 12 | 0–60 | Ignored until evidence extraction is on. |
| Quote max chars | evidence.quoteMaxChars | integer | 2000 | 100–12000 | Ignored until evidence extraction is on. |
| Require citations | evidence.requireCitations | boolean | on | — | Asks the answer to cite sources. An answer can still fail that check. |
| not given its own stage title | evidence.showAllRankedChunks | boolean | off | — | Serialized. It does not add a sixth stage. |
| Relevance filter prompt | policySnapshot.relevancePrompt | string | locale default text | max 12000 | Omitted when equal to the English default. |
| Evidence selection prompt | evidence.promptGuidance | string | locale default text | max 12000 | Ignored until evidence extraction is on. |
| Max files to analyze | policySnapshot.maxDocuments | integer | 5 | 1–30 | How many documents enter analysis. |
| Paragraphs per file | policySnapshot.maxParagraphsPerDoc | integer | 8 | 1–30 | Paragraph cap per analyzed document. |
| Max content chars | policySnapshot.maxContentChars | integer | 2000 | 200–12000 | Character budget for analysis prompts. |
| Analysis max tokens | policySnapshot.analysisMaxTokens | integer | 2000 | 100–32000 | Token budget for per-document analysis. |
| Document analysis prompt | policySnapshot.analysisPrompt | string | locale default text | max 12000 | Omitted when equal to the English default. |
| not a stage title | policySnapshot.analysisOutputHint | string | empty | max 6000 | Sent only when you type one. Empty is omitted. |
| Synthesis max tokens | policySnapshot.synthesisMaxTokens | integer | 2000 | 100–64000 | Token budget for the final answer. |
| Answer synthesis prompt | policySnapshot.synthesisPrompt | string | locale default text | max 12000 | Omitted when equal to the English default. |
| not a stage title | policySnapshot.synthesisOutputHint | string | empty | max 6000 | Sent only when you type one. |
| not a stage title | guarantees.embedGuaranteeN | integer | 4 | 0–100 | Serialized. No separate lab stage is named for it. |
| not a stage title | guarantees.ceGuaranteeSources | integer | 3 | 0–100 | Serialized. No separate lab stage is named for it. |
| not a stage title | guarantees.entityGuaranteePerSource | integer | 2 | 0–100 | Serialized. No separate lab stage is named for it. |
API-only objects that are not rows above: chunkRoles and discovery (field weights and paragraph discovery). They can be accepted by the schema. The lab does not give them these stage labels.
Save and the next run
The form starts as an unsaved default. Save policy stores the name and the snapshot the form built. The next run sends that snapshot. This guide does not say that a saved id alone loads the stored snapshot from the server. A prompt is omitted from the snapshot only when its text equals the English default. The Japanese default text differs, so it is sent. Identifier spelling stays question, count, and searchTopK.
Examples
These are not presets. To narrow Search only, set Search results topK to 10. Answer results topK stays 30. To ground a shorter answer, leave evidence extraction on and set Primary evidence max to 4. Latency and tokens may drop. This does not say the answer gets better.
Screenshot
The lab frame cat-policy-lab-en is open. Per-stage frames are open too.